RAG Application Development Company
Retrieval-augmented generation over your documents and systems: answers with sources, access rules and a known cost per answer.
Our RAG Application Development Services for Enterprise AI Solutions
RAG Consulting and Generative AI Strategy
We find the use cases where retrieval pays off and audit your data sources. A 2-week discovery ends with a fixed scope and price.
Custom RAG Development and RAG Architecture Design
Custom RAG development starts with the RAG architecture: what to index, how to search it and which model writes the answer.
RAG Pipeline Development and Data Ingestion
Connectors pull documents from wikis, drives, help desks and databases, clean them and keep the index in sync with every edit.
Vector Database and Hybrid Search Implementation
A vector database such as pgvector or Elasticsearch, with vector search and keyword search combined, so exact terms and product codes still match.
RAG System and LLM Integration
LLM integration with OpenAI GPT, Anthropic Claude or Google Gemini behind one interface, so you can switch models. Your product reaches it through an API.
RAG System Optimization, Migration, and Support
We take over a slow or costly system, measure it, then fix retrieval, prompts and spend. One agent run went from $400 to about $30.
Discuss your RAG project requirements
RAG Development Services & Solutions We Build
One retrieval core, different products on top. These are the RAG solutions clients ask us for most often.
Enterprise Knowledge Base and AI Search
AI-powered search across knowledge bases, wikis and file shares that answers in plain language and links to the page it used.
RAG-Powered AI Chatbot for Customer Support
A customer support bot that answers from your help content and admits when it cannot. For a telecom operator it covers 80% of request topics.AI chatbot development
Document Q&A and Intelligence Systems
Questions over contracts, policies, reports and manuals, scanned PDFs and tables included. Each answer quotes the clause or page it is based on.
Enterprise AI Assistants for Internal Teams
Assistants for sales, support, legal and operations that read the business data your systems already hold, within each user's permissions.
Agentic RAG and AI Agent Development
Agents that retrieve what each step needs, call your APIs and cite their sources. We rebuilt one this way for a US cybersecurity company.AI agent development
When Businesses Need Custom RAG Development Services
Most teams come to us with one of these five problems. Each one is a retrieval problem before it is a model problem.
Teams Cannot Find Relevant Information Quickly
The relevant information sits in hundreds of documents and a few people's heads. Staff search, ask in chat and wait, and customers wait too.
Fragmented Business Data Across Multiple Sources
Policies in a wiki, prices in an ERP, history in a CRM. A retrieval pipeline reads all of them and keeps one index in sync.
AI Hallucinations and Unreliable LLM Answers
A model without sources fills gaps with confident guesses. Retrieval with citations gives it facts, and a rule tells it to say when sources are silent.
Generic LLMs Lack Context About Your Data
Public models know the internet, not your products, contracts or customers. Retrieval hands them your data at question time, with no model training.
Limited Integration of AI with Existing Enterprise Systems
Experiments with AI stall when the tool cannot see your CRM, ERP or help desk. We connect retrieval to the systems and sign-in you run.
Sometimes the best RAG project is the one we talk a client out of.
If the knowledge base is small, a vector database, a sync pipeline and their upkeep cost more than they return, and they bring bugs of their own.
If people search by exact names, like a drug by its nomenclature or a substance by its exact entry, plain text search beats semantic search.
When RAG does fit, the type decides the outcome: classic, graph RAG or agentic RAG, plus the retrieval techniques around it. Pick the wrong one and the money buys very little.
 Oleg KopachovetsFounder and CEO, ProCoders
Key Features of Custom RAG Solutions
What a production system needs beyond a demo. Retrieval quality decides most of the result.
- IngestedWiki, PDFs, help desk
- ChunkedBy heading and table
- IndexedVectors and keywords
- RetrievedHybrid search
- RerankedBest passages first
- AnsweredWith citations
Multi-Source Data Ingestion and Real-Time Sync
Connectors for wikis, drives, help desks and databases, with real time or nightly sync. An edit in the source reaches the next answer.
Semantic Chunking and Vector Search Indexing
Documents split by meaning, headings and tables rather than by fixed length, then embedded and indexed for vector search.
Hybrid Search and Reranking for Retrieval Quality
Keyword and vector search together, then a reranker puts the best passages first. We measure retrieval quality on your own questions.
RAG Evaluation, Monitoring, and Analytics
A set of real questions runs on every change. Dashboards show answer quality, unanswered questions, latency and cost per answer.
Context-Aware Answers Grounded in Source Citations
Answers grounded in retrieved passages, with a link to the page or clause. Context-aware follow-ups keep the thread of the conversation.
Role-Based Access Control and Permission-Aware Retrieval
Access control applies at search time: users retrieve only what they may open in the source system. Personal data stays out of the logs.
Web, Mobile App, and Chatbot Interfaces
A search page, a chat inside your product or mobile app, a Slack or Teams bot, or an API for your own front end.
RAG Technology Stack and Enterprise Integrations
We choose the stack for your data, your cloud and the team that will own the system after launch.
Large Language Models and Embedding Models
We test large language models on your questions and keep the one that passes at a cost you accept. Switching providers later is a config change.
- OpenAI GPT
- Anthropic Claude
- Google Gemini
- Meta Llama
- OpenAI embeddings
Vector Databases and Search Engines
pgvector when your data already lives in PostgreSQL, a managed index when scale calls for one. The choice depends on your cloud and query load.
- pgvector
- PostgreSQL
- Weaviate
- Pinecone
- Elasticsearch
- OpenSearch
- Dataverse search
Data Sources, Knowledge Bases, and Enterprise System Integration
Connectors to the wikis, drives, help desks and CRMs you already run, with the sign-in you already use.
Assistants also read ERP, WMS and TMS data, the systems we connect for logistics clients.Logistics Software Development Services
- Jira
- Zendesk
- Intercom
- Salesforce
- HubSpot
- Microsoft Entra External ID
RAG Frameworks and Cloud Infrastructure
Standard frameworks instead of hand-written loops, so a new engineer can read the code. We deploy in your cloud account, inside your network rules.
- LangChain
- LlamaIndex
- Vercel AI SDK
- Microsoft Copilot Studio
- Azure
- AWS
- Google Cloud
Discuss your RAG integration needs
Benefits of Custom RAG Development for Business
What changes when answers come from your own content, with the sources attached.
Telecom support agent · Cost per answer
Security agent rebuild · Time per run
Security agent rebuild · Cost per run
Faster Access to Business Knowledge
Staff and customers get an answer in seconds instead of digging through folders or waiting for a colleague.
Higher Accuracy with Fewer Hallucinations
Answers come from retrieved passages, and the system says so when the sources have nothing. Each claim links to where it came from.
Always Up-to-Date Answers Without Model Retraining
Change a document and the next answer uses it. No fine tuning run and no retraining, only a re-index.
Scalable and Cost-Efficient AI Solutions
The model reads only the passages a question needs. A telecom support agent went from about 10 cents to about 1 cent per answer.
Data-Driven Decisions with Traceable Answers
Every answer names its sources, so a manager can check a figure before acting on it. Unanswered questions show where your documents have gaps.
Our RAG Development Service Process
Five steps from a use case to a monitored system, with a demo every week.
Discovery, Use Case Assessment, and Data Audit
Two weeks to pick the use case, sample your data sources and write the test questions. You get a scope and a fixed price.
RAG Architecture Design and Technology Selection
Index, search method, model and hosting chosen against your questions, your data rules and a cost per answer target.
Data Preparation, Retrieval Pipeline, and LLM Integration
Connectors, cleaning and chunking first, then search, reranking and the model, wired into your product in weekly increments.
Testing, Evaluation, and Deployment
Real questions, prompt injection and data leak tests, then load tests before launch. The telecom agent passed 4,000 test requests without a prompt leak.
Monitoring, Optimization, and Continuous Improvement
After launch we track quality, gaps and spend, tune retrieval and prompts, and rerun the evaluation set on every change.
RAG Services Development Company Engagement Models
Choose how much of the work you hand over. You can switch models as the system grows.
Dedicated RAG Development Team
A dedicated team that owns your system end to end. It starts from $5k per month: one engineer with fractional QA and PM.
Dedicated development teamTeam Augmentation for RAG and AI Projects
One or two senior engineers join your team for retrieval, evaluation, connectors or APIs, with a shortlist in 72 hours.Hire AI developersHire backend developers
IT staff augmentationEnd-to-End RAG Application Development Service
We run it from discovery to launch and support, for a fixed price set after a 2-week discovery.
Discovery phase
Why Choose ProCoders as Your RAG Application Development Company
Custom AI Built Around Your Business Data and Workflows
Custom AI that starts from your questions and documents, not a platform's template. You own 100% of the code, prompts and indexes.
AI Development and Machine Learning Expertise
Senior engineers who ship retrieval, AI agents and the machine learning around them: embeddings, rerankers, evaluation. We say when artificial intelligence is the wrong tool.
RAG Development Company for Enterprises: Integration Expertise
Enterprise AI has to fit your cloud, sign-in and security review. Our telecom agent runs inside the operator's own Microsoft environment in Azure.
ISO 27001-Certified Security for Your Business Data
ISO 27001 certified processes audited every year, an NDA before we see your data, and USD 1M cyber and professional liability cover.
Flexible Development Teams
Start a pilot with two engineers and add people as usage grows. Engineers start in 48 hours, with 5+ hours of US and EU overlap.
Long-Term Support and Scalability for RAG Systems
Content, models and prices change every few months. With a 5-year median engineer tenure, the people who built it stay to re-index, retest and upgrade.
Our RAG and AI Development Case Studies
Two AI systems we moved to retrieval, with the numbers before and after.
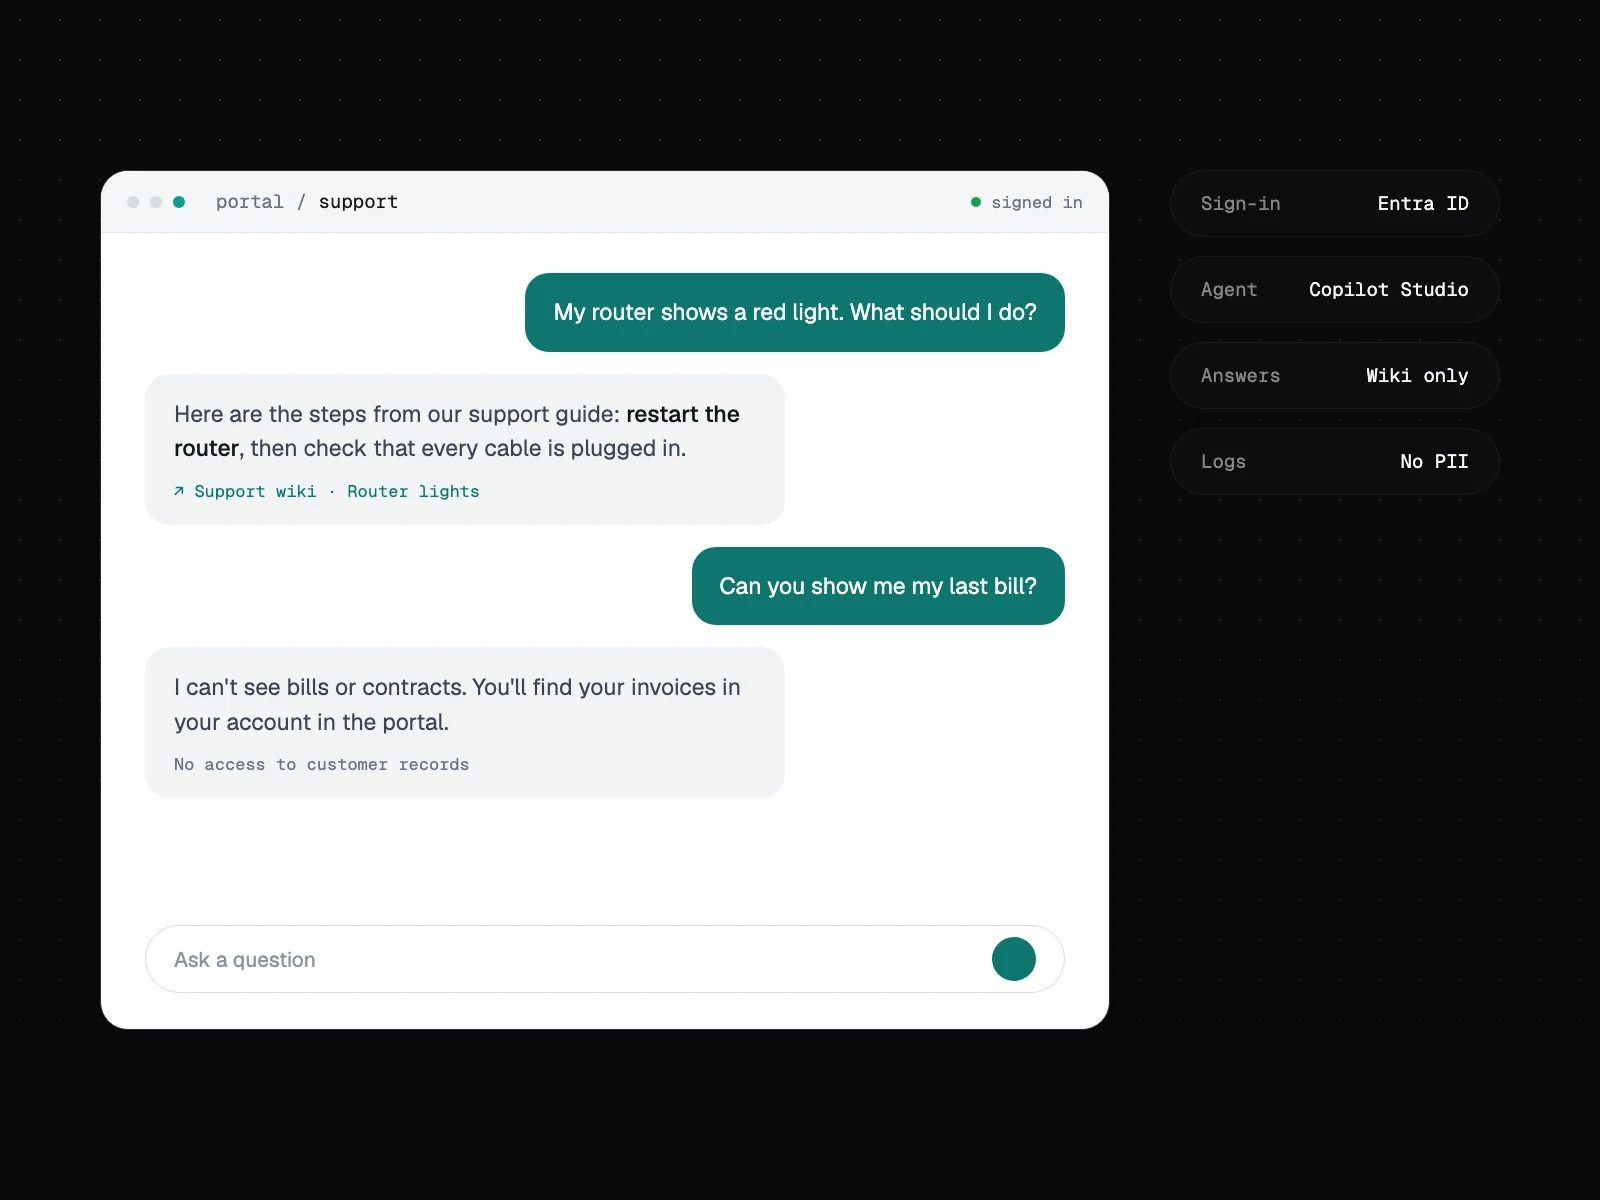
Support agent on RAG: about 10 cents to about 1 cent per answer
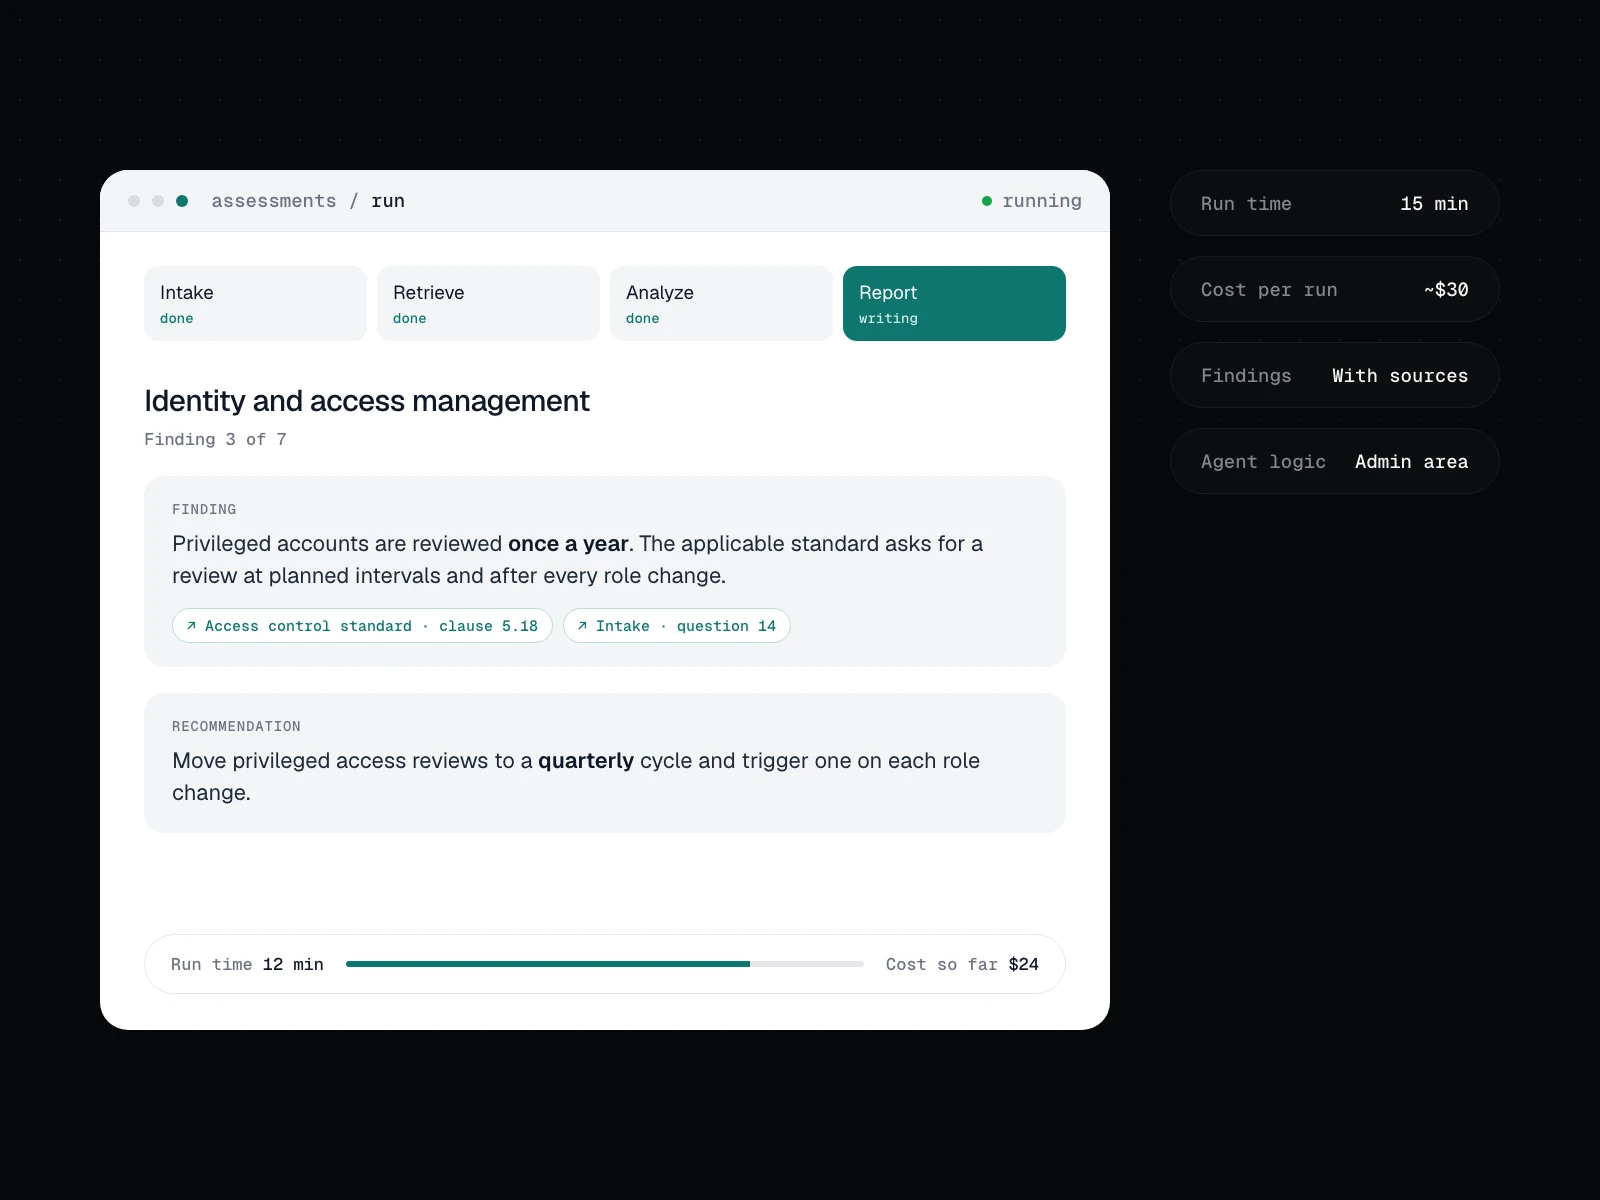
Agent rebuilt with retrieval: 3 hours to 15 minutes per run
What Our Partners Say
"Overall, we are very pleased."
"They are very proactive and we really appreciate their constant suggestions and feedback."
"We maintain our partnership and team dynamics with no plans to end any time soon."
 Founder & CPO, Roth River
RAG Application Development Cost Factors
RAG application development cost starts from $12k for a Sprint project, and a dedicated team runs from $5k per month.
Six factors move the number. We price them in a 2-week discovery and fix it in the contract.
Use Case Scope and Solution Complexity
One search box over one wiki costs far less than an agent that reads ten systems and acts on them.
Retrieval Architecture and Vector Database Choice
pgvector inside your existing database is cheaper to run than a separate cluster. Hybrid search and reranking add build time and lift answer quality.
LLM Selection and Enterprise System Integrations
The model's price per token sets the running cost, and every connected system adds integration and test work.
Data Volume, Knowledge Sources, and Number of Users
A few thousand clean pages index quickly. Millions of scanned files, many languages and heavy traffic need more engineering.
Security and Compliance Requirements
Permission-aware search, data residency, personal data masking and audit logs add design and review time. We plan them in from the start.
Deployment, Monitoring, and Ongoing Support
Hosting, model usage, monitoring and re-indexing after launch are part of the total. We quote them next to the build.
Get a project cost estimate
RAG Development Services FAQs
Not here? Write the question in the form. We answer in one working day.
Can retrieval augmented generation handle scanned PDFs, tables, images, and multilingual content?
Yes, with the right ingestion. Scanned PDFs go through OCR, tables are parsed into rows the model can read, and images get text descriptions. Multilingual content works with multilingual embedding models, and we test retrieval in every language you need.
Can RAG be combined with fine-tuning for domain-specific AI?
Yes. Retrieval supplies current facts, and fine-tuning teaches the model your format, tone or domain terms. Most projects start with retrieval alone because it is cheaper to keep current. We add fine-tuning only when evaluation shows retrieval is not enough.
Should we build a custom RAG solution or use an off-the-shelf AI platform?
Use a platform when your content sits in one tool and its built-in assistant passes your test questions. Build custom when you need several sources, permission rules, your own interface, cost control or code you own. Our telecom agent runs on Microsoft Copilot Studio, with retrieval and security tuned for the operator.
How long does it take to develop a RAG application?
A focused pilot takes weeks: our telecom support agent reached a working prototype in 6 weeks and production readiness in 2 months. Many sources and strict security take longer. A 2-week discovery gives you the exact timeline.
Who owns the source code, vector indexes, and RAG pipelines after delivery?
You do. The contract transfers 100% of the code and IP, including pipelines, prompts, evaluation sets and indexes, and includes an NDA. The index can run in your own cloud account.
More on retrieval, AI agents and AI inside the products you already run.
Discover More Services We Provide
Other ways to work with our engineers:
Discuss your RAG project
Tell us about your documents, users and systems. You get a scope, a timeline and a price from the RAG application development company that will build it.